Personal Product
Vocabulary Builder (Personal Product)
A cross-platform vocabulary learning app deployed on web and android, built with TypeScript, Expo and Domain Driven Design. Features include spaced repetition reviews (SM-2), hands-free podcast narration, bilingual (EN/FR) word tracking with definitions and context sentences, and offline-first backup with ZIP-based sync, all from a single codebase with zero cloud dependency.
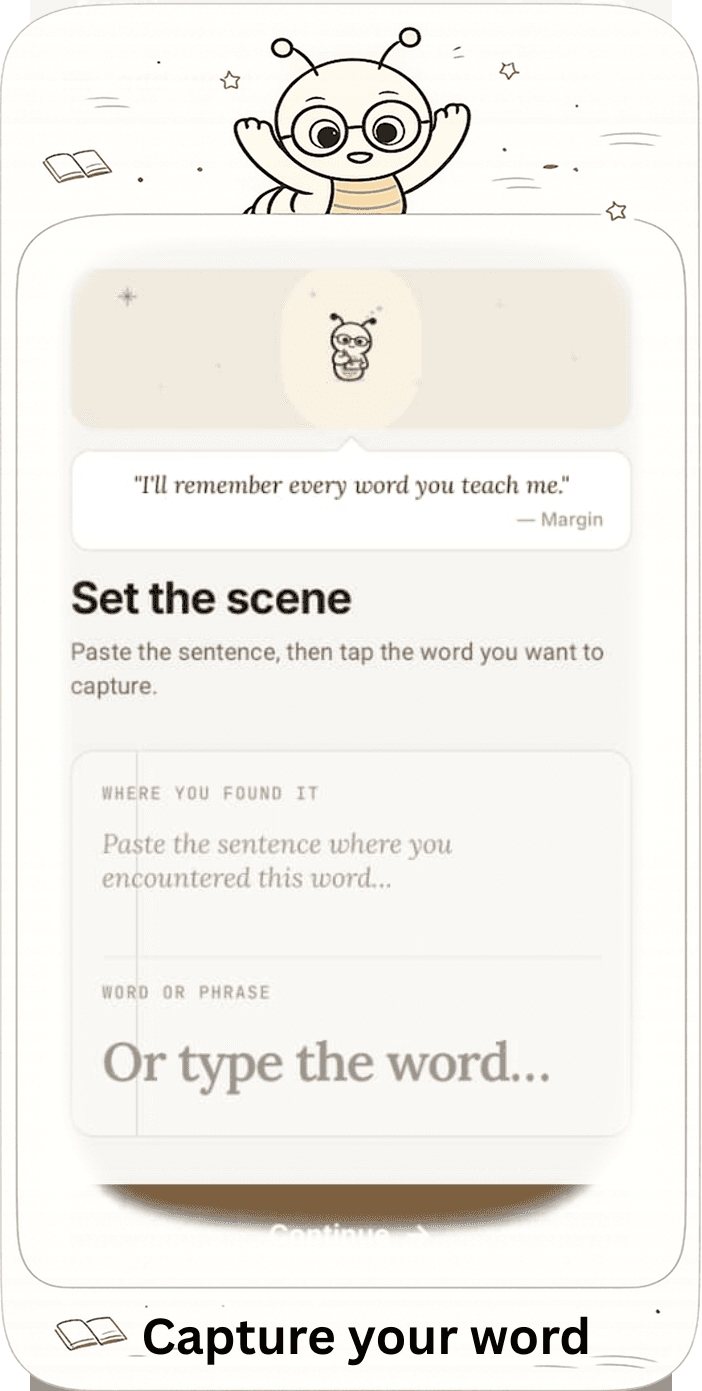
Add words with context
- Captures the core word-entry workflow for adding vocabulary with definitions and examples.
- Supports bilingual EN/FR tracking from the same form-driven experience.
- Stores words locally through the shared domain model and repository layer.
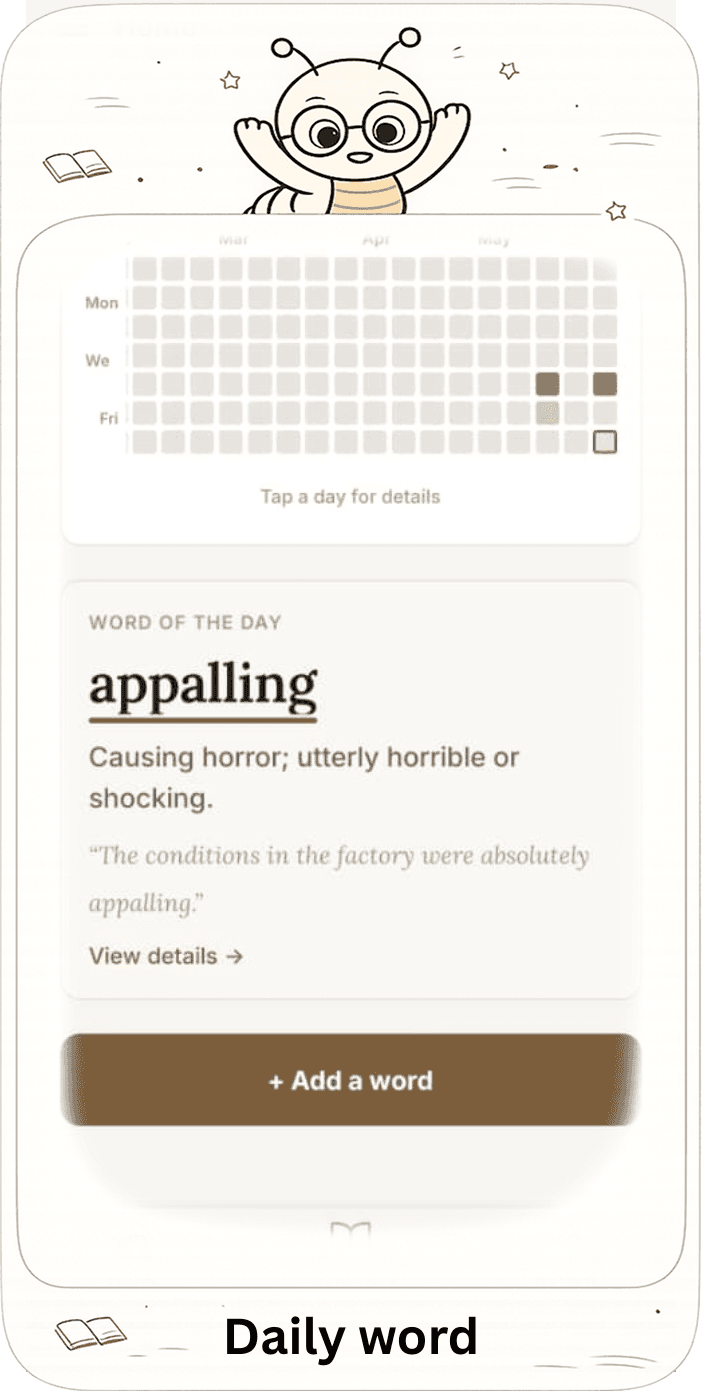
Word of the day
- Highlights a daily vocabulary prompt to make returning to the app feel useful immediately.
- Surfaces definitions, translations, and context in a compact mobile-first view.
- Reinforces regular study habits without requiring a full review session.
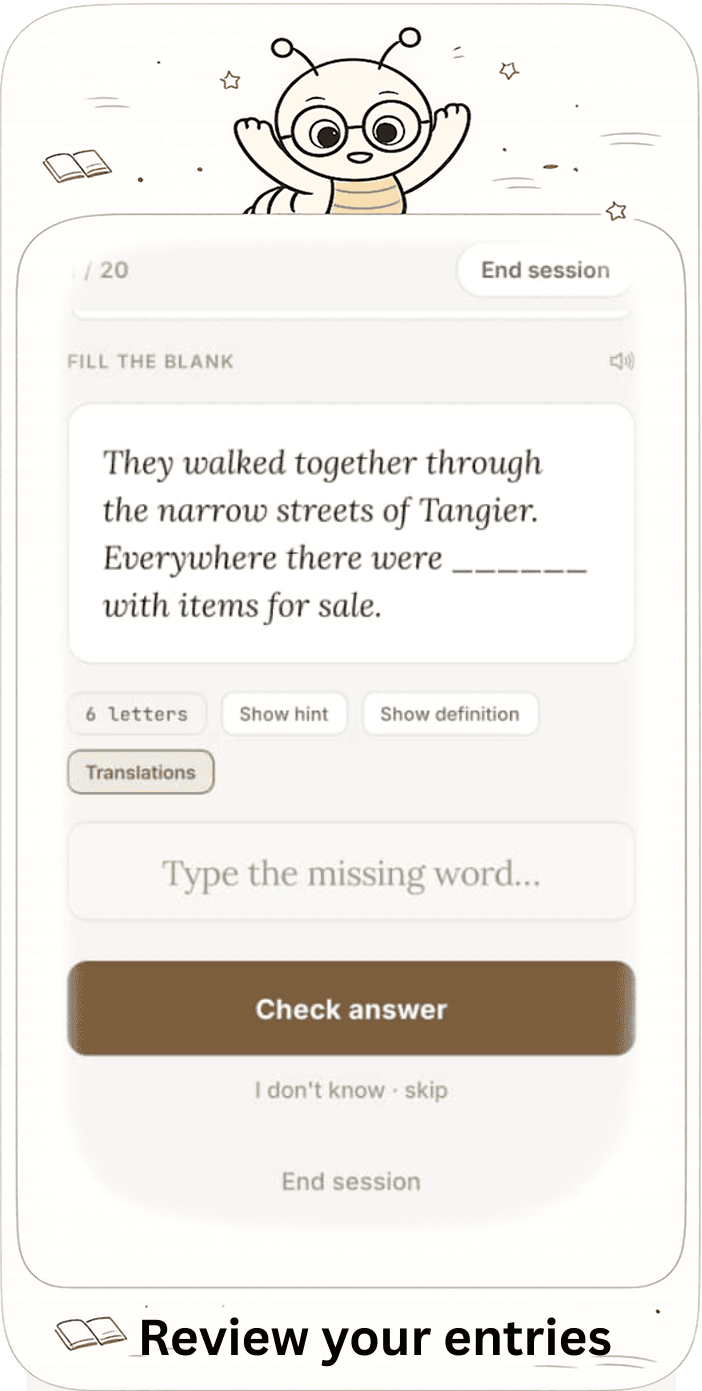
Review your words
- SM-2 scheduling prioritizes words that are due instead of showing a flat flashcard queue.
- Review flow tracks recall quality and updates the next review date automatically.
- Built to support daily retention with minimal manual organization.
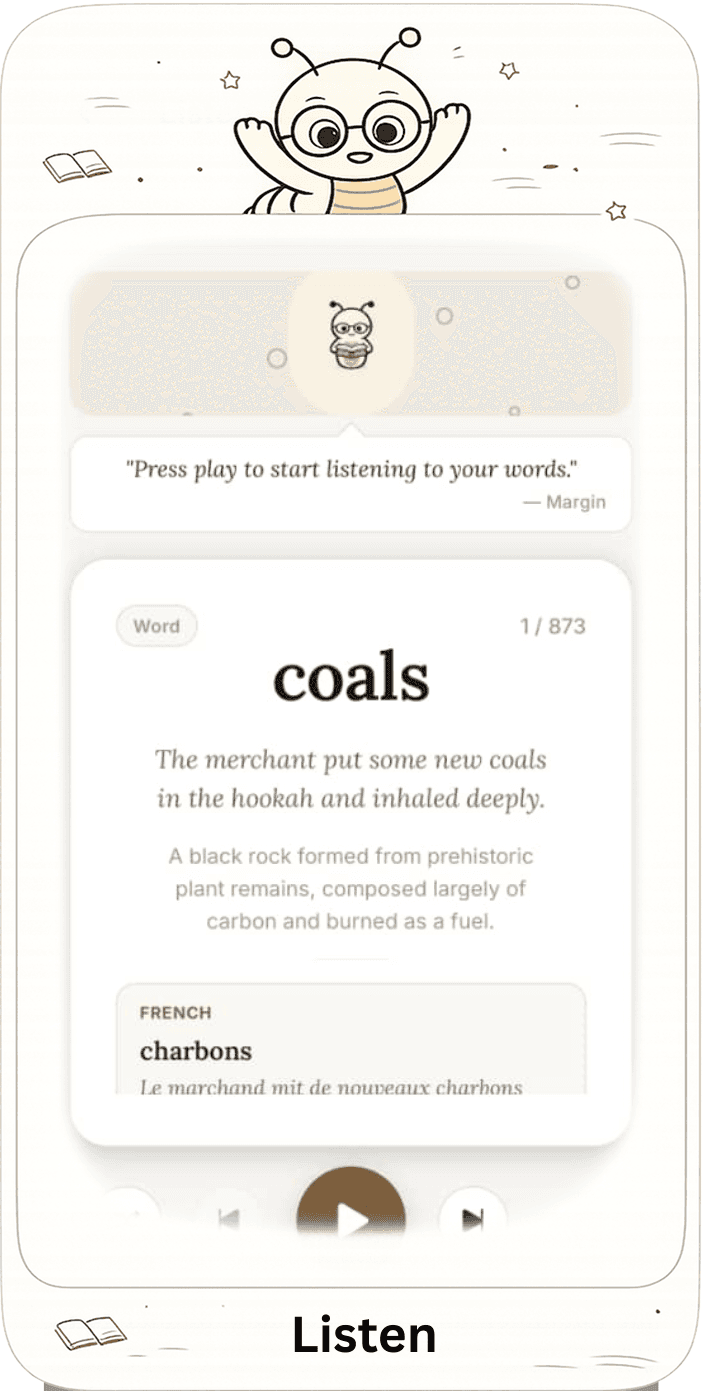
Listen mode
- Hands-free podcast narration lets users review vocabulary while walking, commuting, or resting.
- Reads saved words with definitions and context so review is not limited to screen time.
- Reuses the same vocabulary data as the visual review flow.
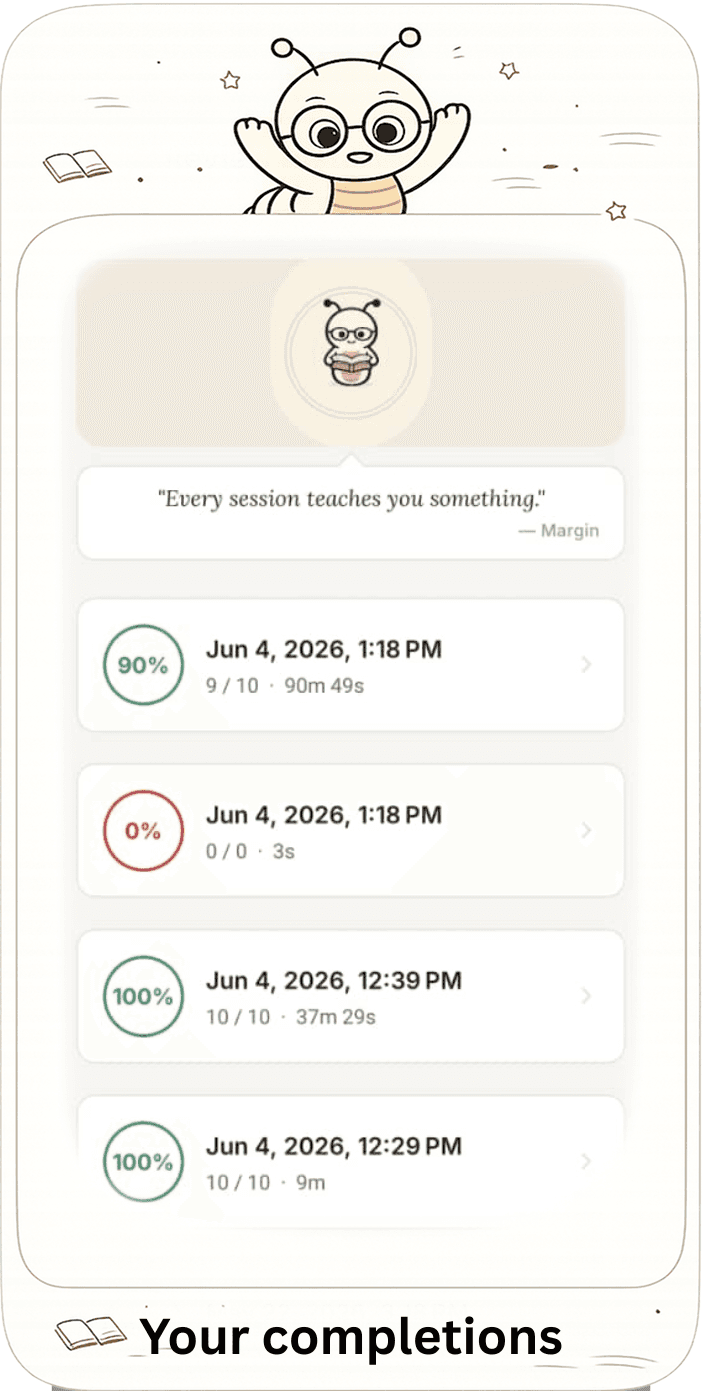
Learning statistics
- Progress views summarize review activity, streaks, and vocabulary growth.
- Gives learners feedback on consistency and retention over time.
- Keeps personal analytics local with the rest of the offline-first app data.
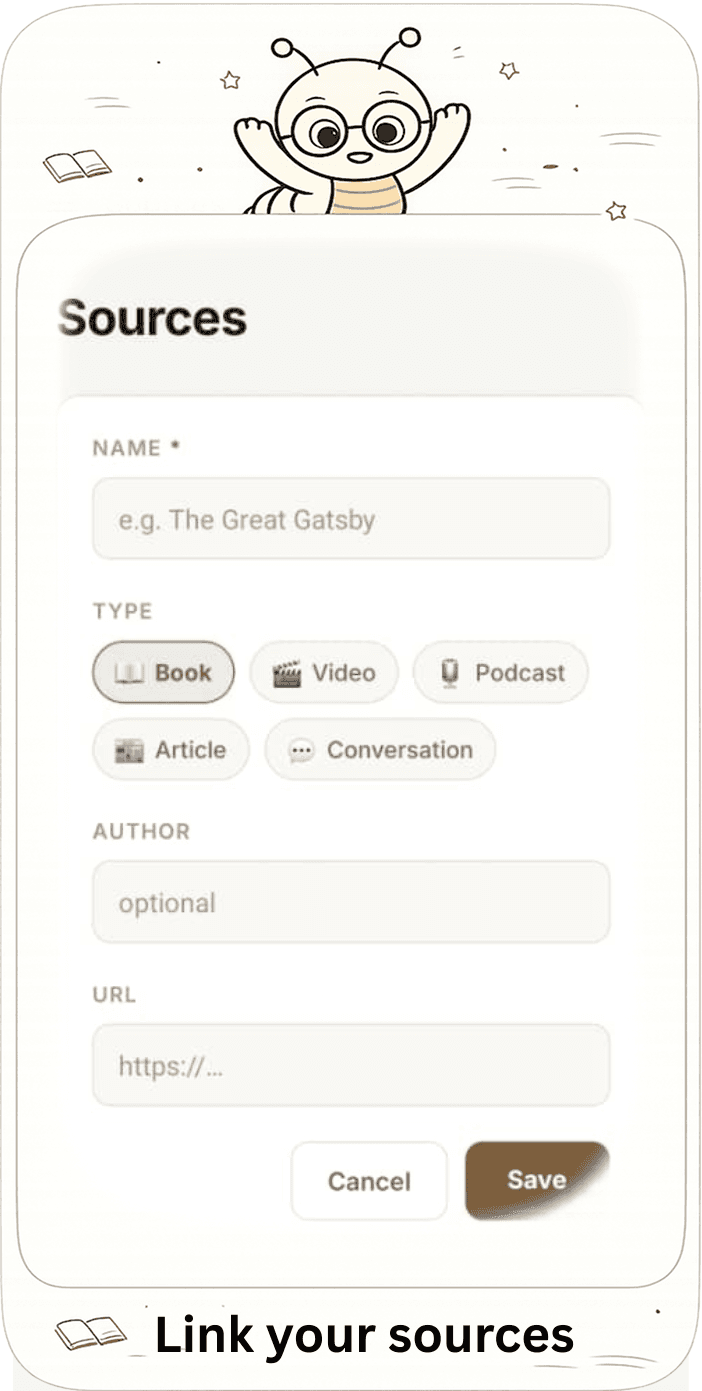
Source-based organization
- Words can be grouped by source so learners remember where vocabulary came from.
- Supports books, articles, videos, courses, or any custom learning context.
- Source metadata is part of the clean domain model instead of UI-only tagging.
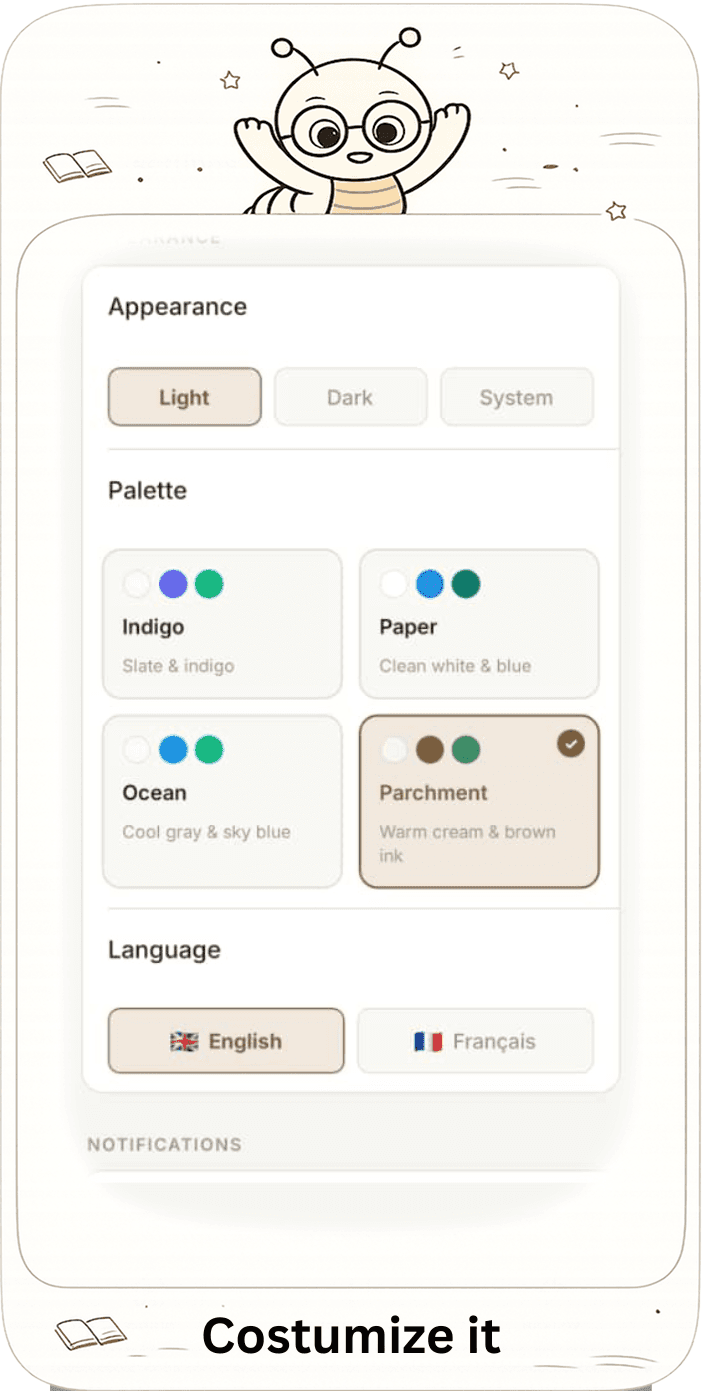
Offline-first backup and preferences
- Backup and restore workflows use ZIP-based sync to avoid cloud dependency.
- Language and app preferences are available from a focused settings screen.
- Native and web storage implementations stay interchangeable behind shared interfaces.
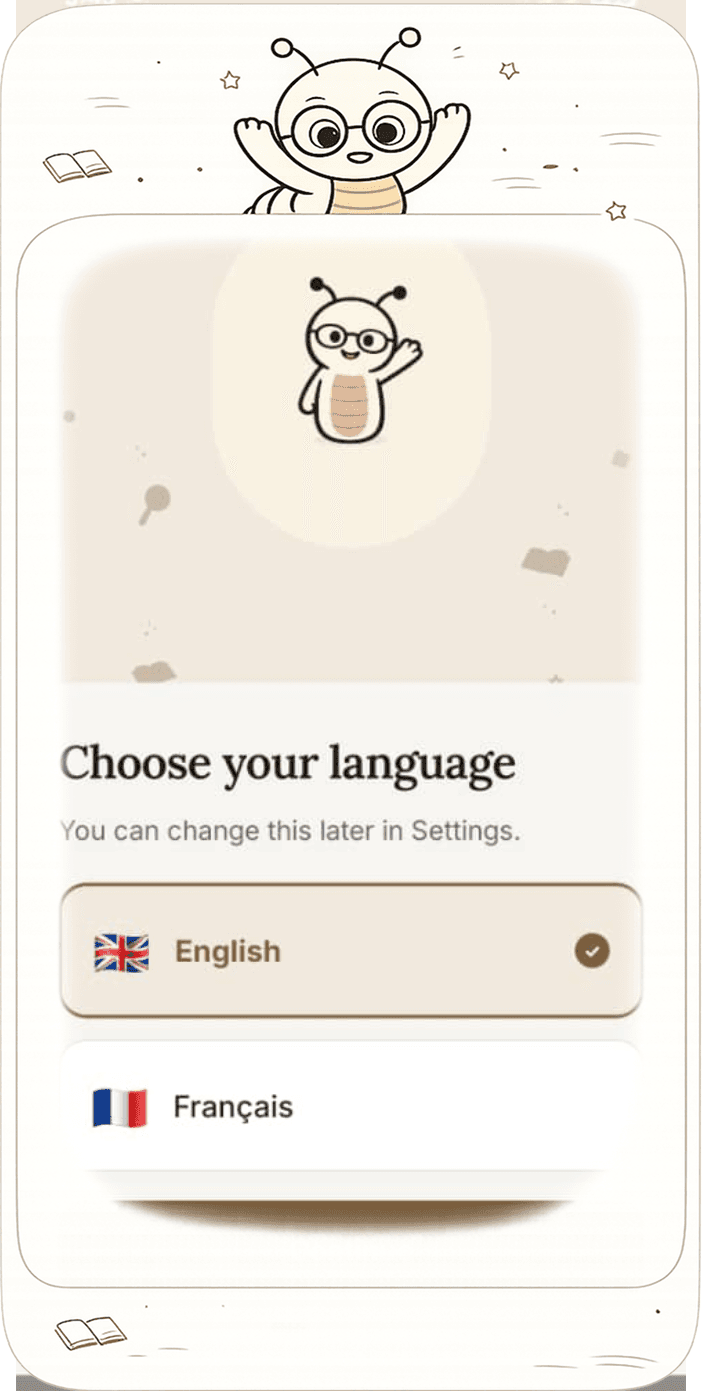
Choose your language
- Onboarding supports English and French usage from the start.
- Language choice connects to the app's localized vocabulary workflow.
- Keeps the first-run experience aligned with the bilingual product scope.
Implementation notes
- Built and shipped this as a personal product to solve my own vocabulary learning workflow, taking it from idea to production on both Web and Android solo
- Deployed on Web and Android from a single TypeScript codebase by applying DDD and clean architecture, swapping SQLite (native) and IndexedDB (web) persistence behind a shared repository interface
- Implemented SM-2 spaced repetition algorithm scheduling daily reviews and a podcast narration mode for hands-free passive review, maximizing retention across multiple study contexts
- Built offline-first backup system with ZIP compression, incremental push/pull sync, and image bundling eliminating cloud dependency and server costs entirely
Featured Projects
Open Source
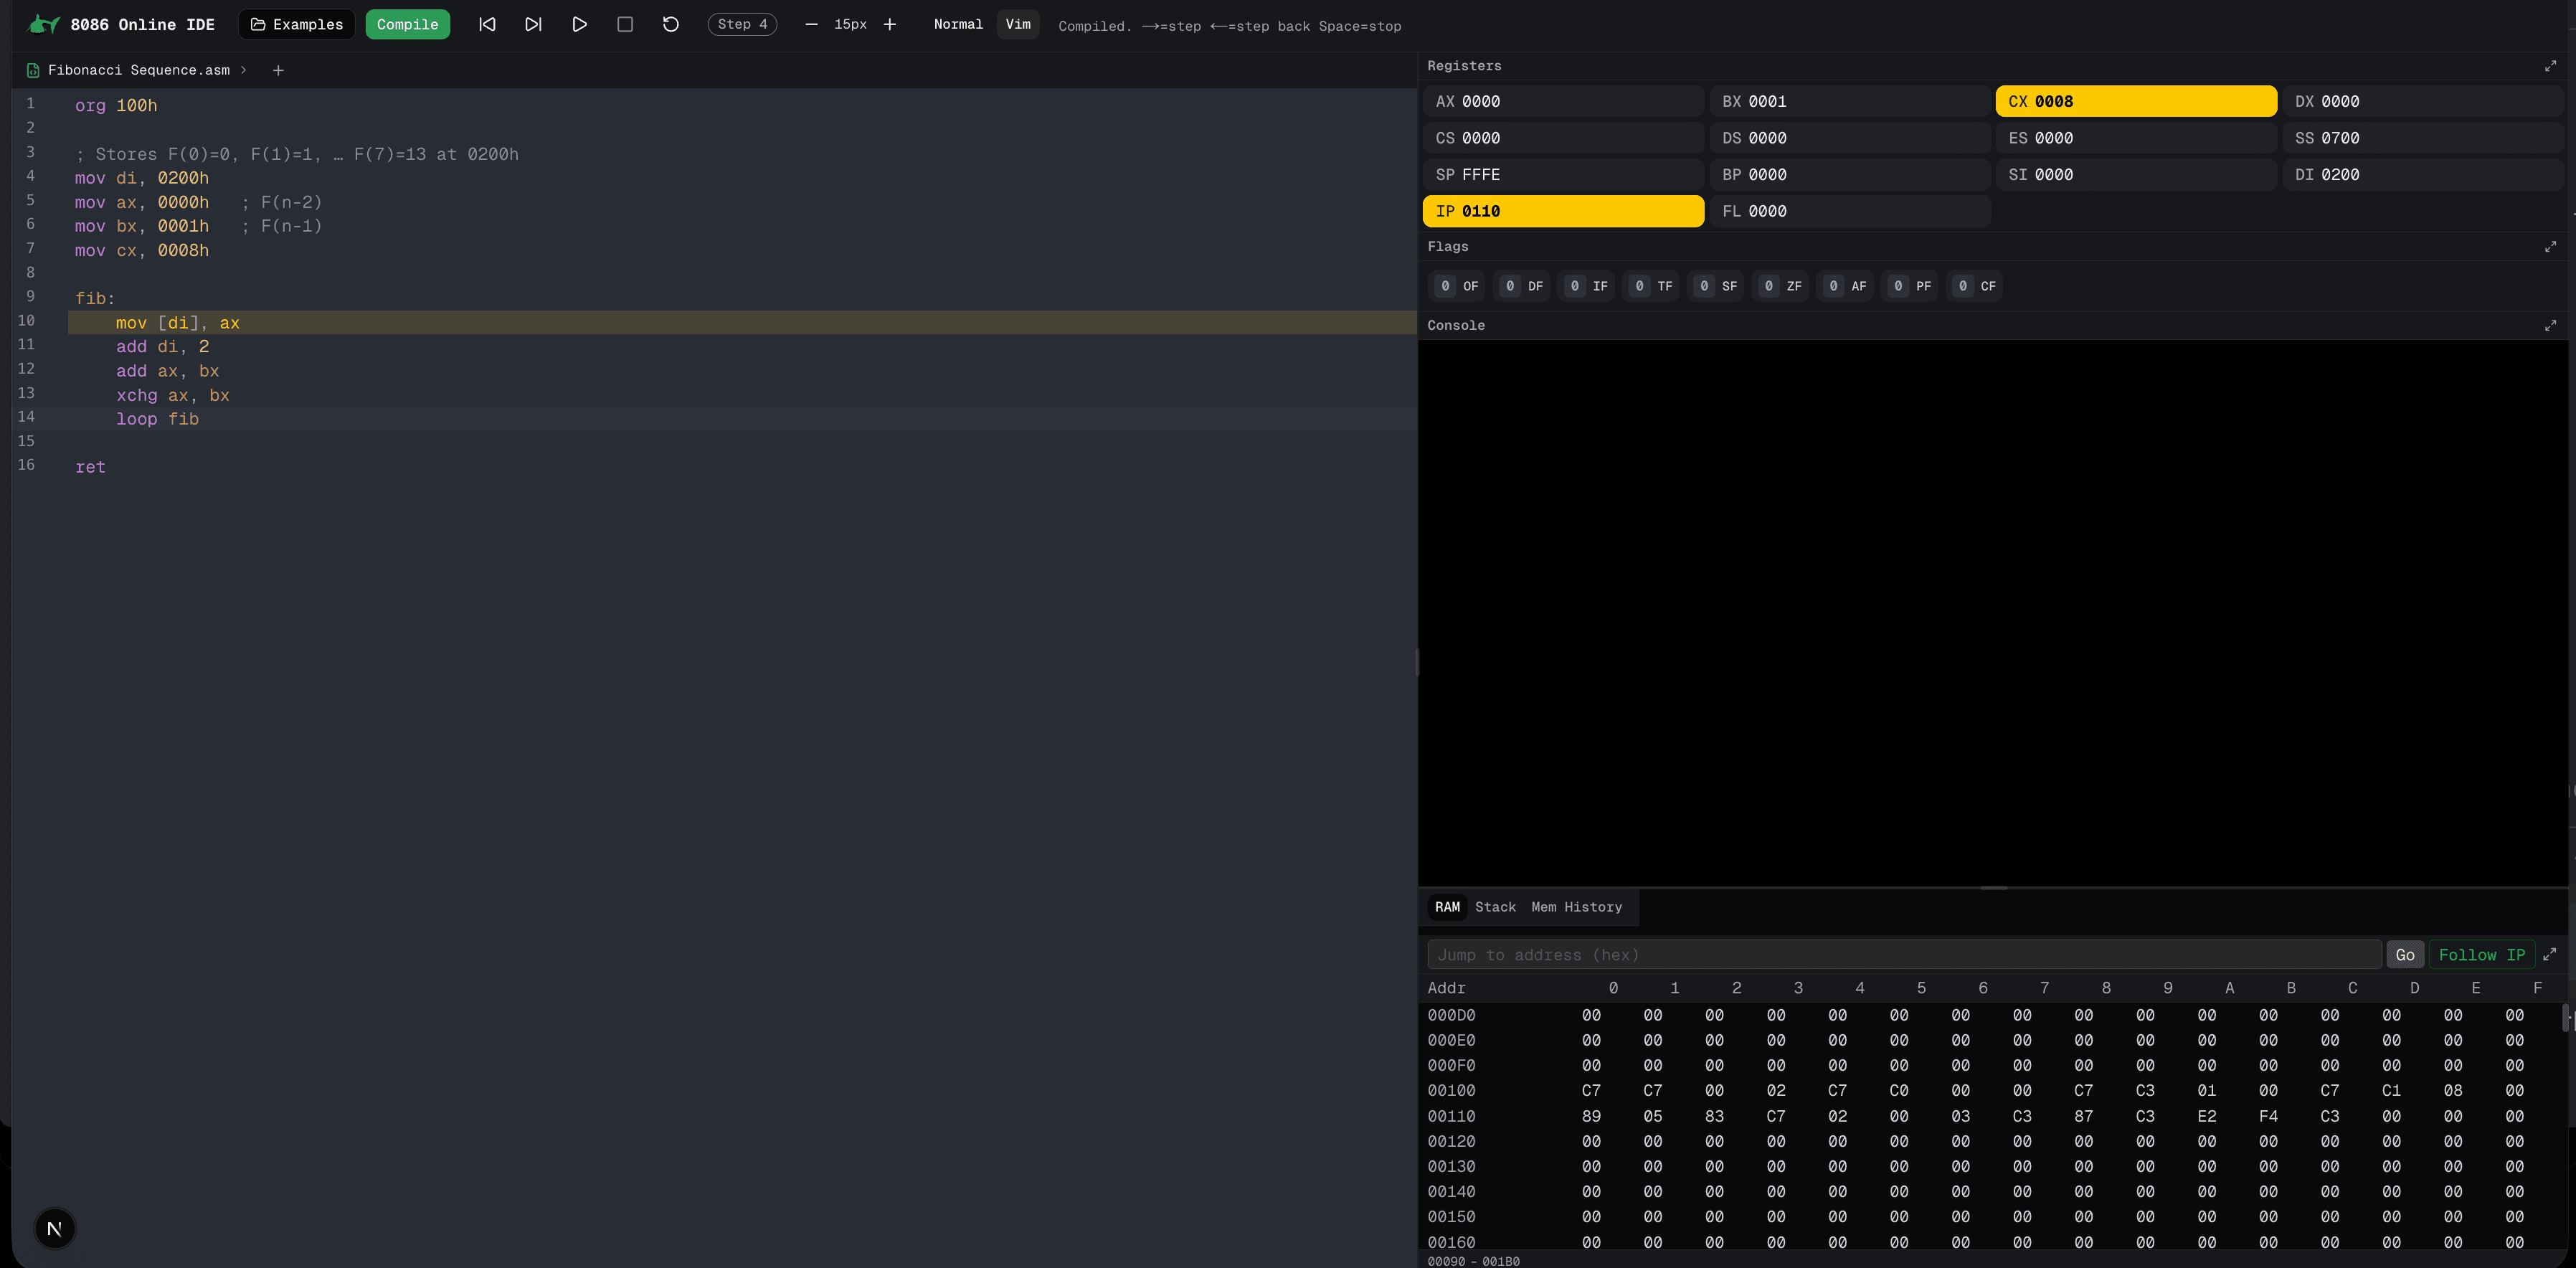
8086 Processor Web Emulator
Open-source Intel 8086 emulator and assembler for the browser (Vanilla JS), built as a second year university project in a team of 6, featuring instruction set simulation and interactive debugging.
- JavaScript
- HTML
- CSS
Thesis Project
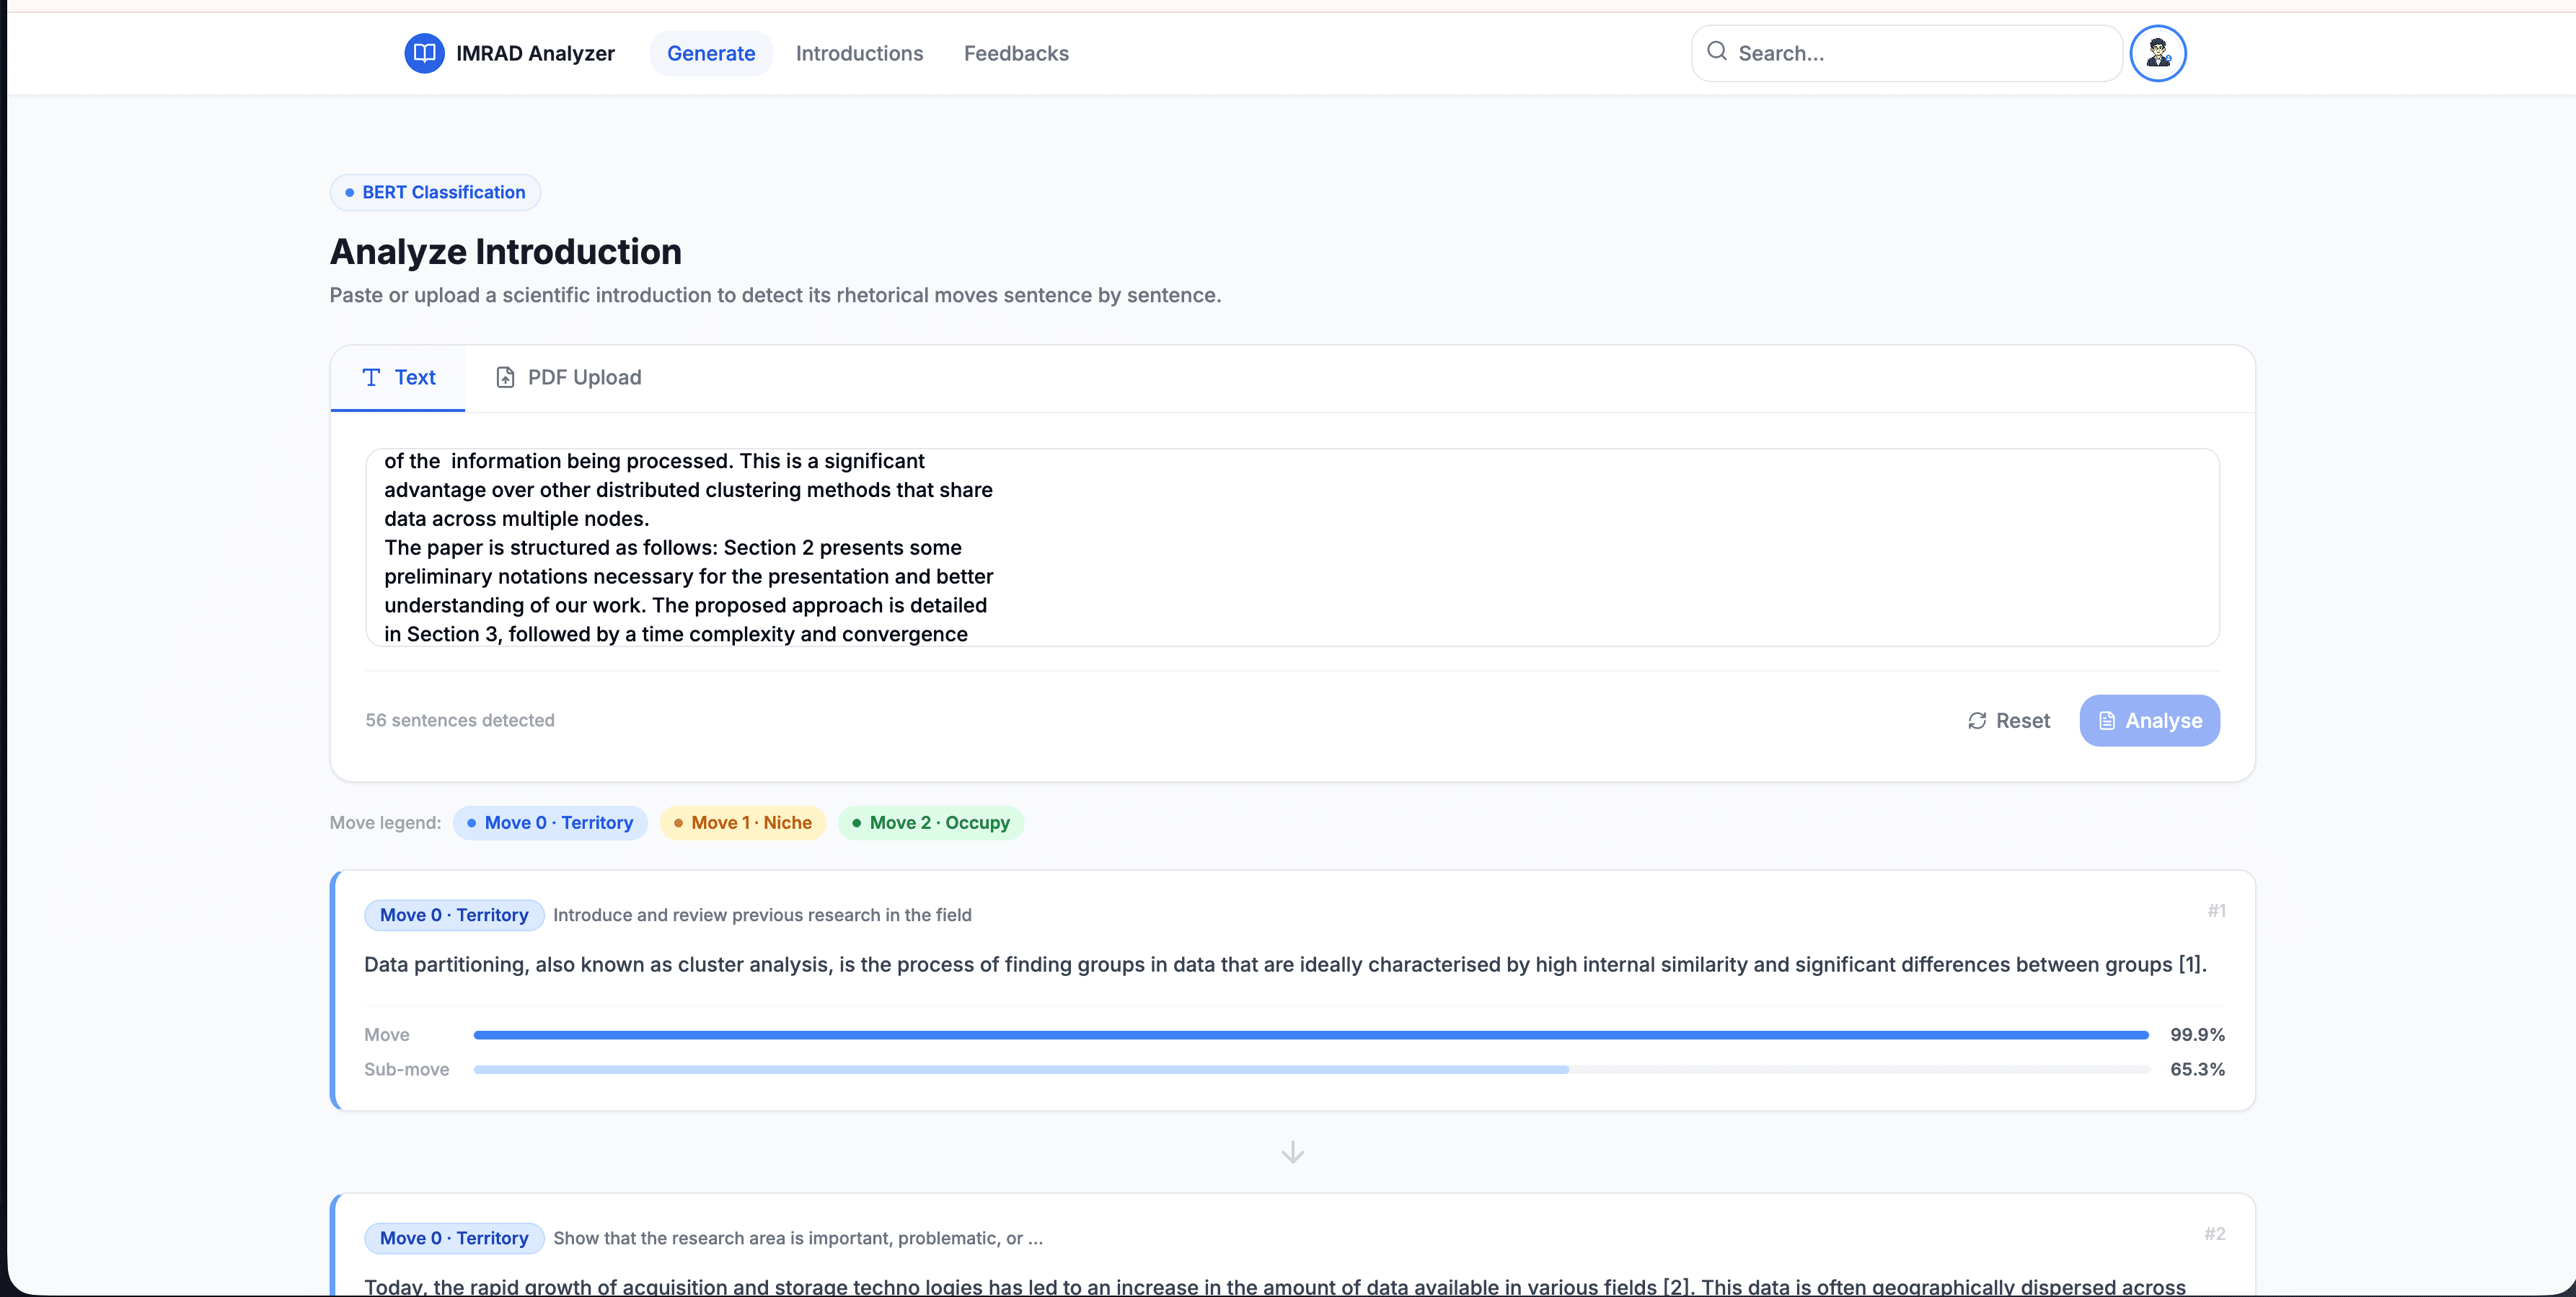
IMRaD Analyzer: Distributed Microservices for Scientific Text Classification
An 8-node microservices platform leveraging BERT and Gemini Pro to classify scientific papers, using a custom 169k-sentence dataset to achieve a 98.21% peak F1-score.
- Next.js
- FastAPI
- BERT
- Gemini Pro
- TF Serving
Let's work together
I'm currently open to new roles, remote-first or international. If you're building something ambitious, I'd love to hear about it.